Voice AI
Amazon Silently Kills Alexa Voice Switching for Older Echo AUX Jacks
Selma Ortiz · 17h ago · 4 min read
Tavus unveiled Griffin, a real-time conversational model that fooled 48 percent of callers into thinking it was human. Voice and video just crossed the line.
By Ray Dalton, Editor-in-chief · Reported off The Decoder
Runs the desk. Allergic to demos that only work on stage.
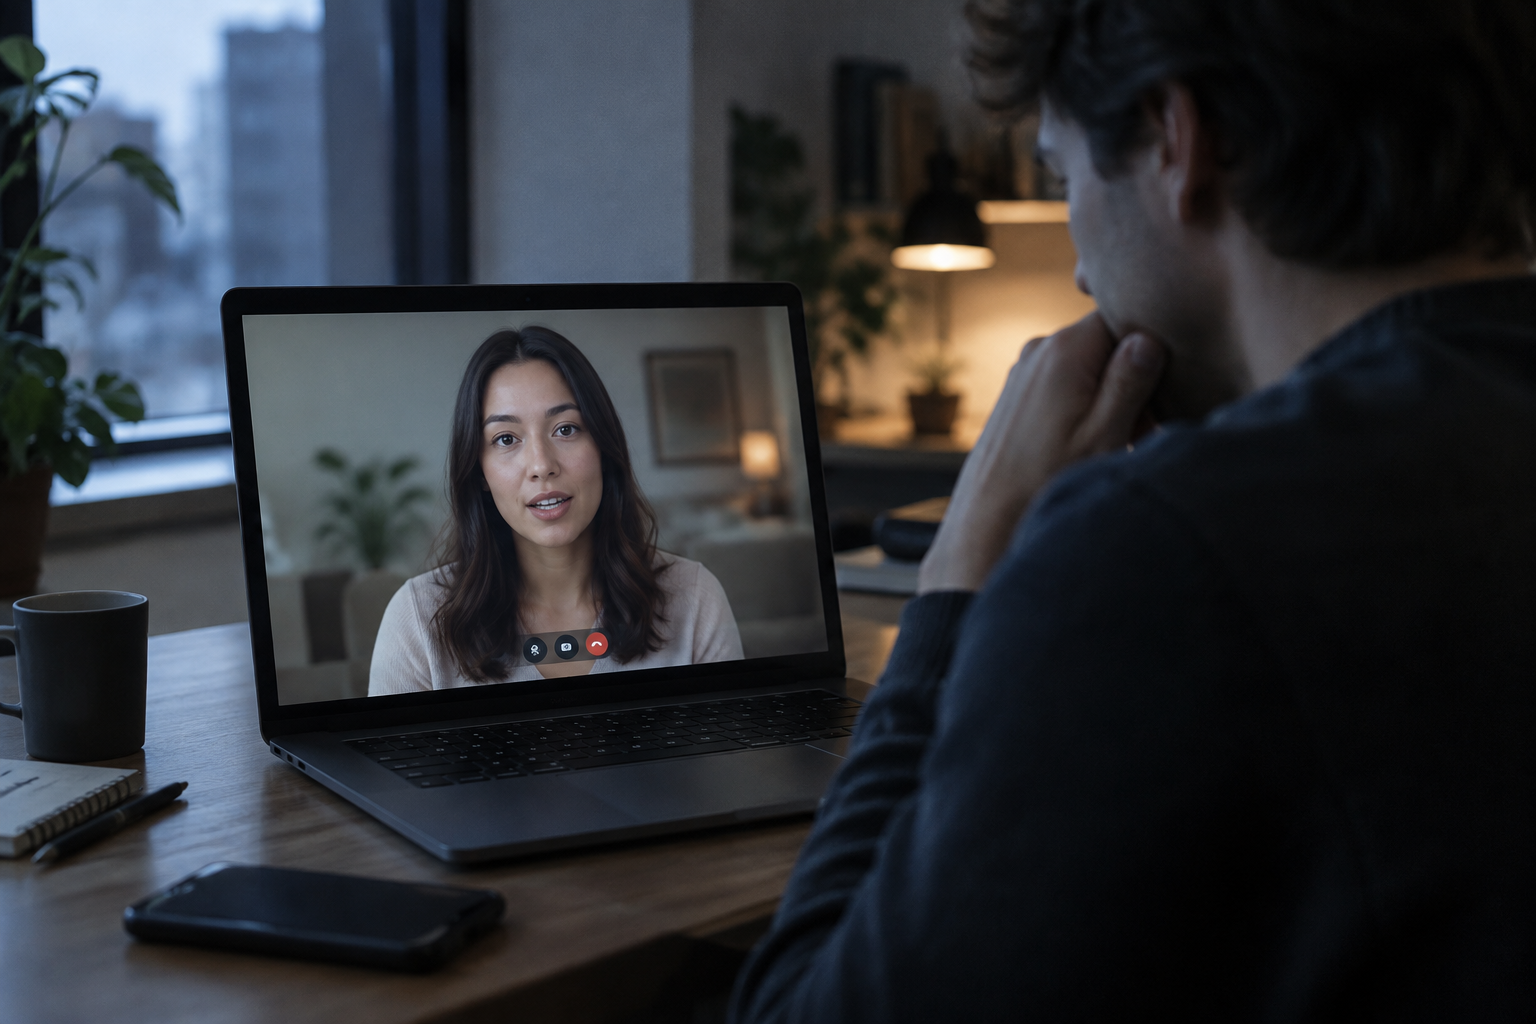
Put a human on a webcam for sixty seconds with an artificial intelligence. Ask them who was on the other side of the glass. Until now, ninety-eight times out of a hundred, they would tell you it was software without blinking.
Tavus just flipped that coin.
In an internal evaluation study, 48 percent of test subjects who completed a one-minute live video conversation with the company's new model, Griffin, concluded they were speaking with an actual flesh-and-blood human being. That is not an incremental nudge. Earlier benchmarked systems topping out at two percent felt like talking to a digital wax figure trapped inside an answering machine. Griffin cleared nearly half the room.
The system runs on what Tavus calls a Human Interaction Model, or HIM. It does not just wait for an audio turn, parse the transcript, and regurgitate synthetic speech over a looping video file. Griffin continuously intakes and emits video and audio simultaneously in real time. It monitors incoming speech, registers facial expressions, tracks the caller's tone of voice, watches hand gestures, and registers natural conversational pauses while generating its own responsive speech and visual behavior on the fly.
In a separate evaluation run through Nvidia testing protocols specifically designed to measure how convincingly human an interactive agent feels during unscripted audio-video dialogue, Griffin posted a score of 3.83 points. Real people in the identical test environment averaged 3.92 points. Before Griffin showed up, the highest score any synthetic conversational agent had ever managed in that Nvidia assessment was 2.80.
"Griffin continuously monitors speech, facial expressions, tone, gestures, and pauses while both ingesting and generating live video in real time."
To keep the blast radius contained, Tavus is not handing the keys to the public just yet. The company released a restricted preview build dubbed Griffin-Lite to an invite-only group of research partners, while locking the flagship model in the vault until engineers address outstanding safety risks.
Tavus did not pull this system out of a weekend hackathon. The San Francisco startup surfaced in 2020, launched by founders looking to crack automated video production. Over six years, the company raised roughly $64 million in venture backing to eliminate the friction of pointing a camera at human operators.
In its early days, Tavus chased the enterprise sales funnel. The initial product suite focused on asynchronous video generation: taking a single recorded video clip of an account executive or marketer, lip-syncing prospective customer names into the footage, and sending thousands of customized pitches to corporate email inboxes. It was clever video mail-merge, but it was strictly one-way communication.
As speech-to-speech models and real-time inference matured, one-way video rendering became a commodity trap. Tavus used its $64 million war chest to pivot into interactive, bi-directional synthetic personas. Instead of pre-rendering a static MP4 file for outbound sales campaigns, the engineering team spent years training pipelines to reduce latency across three separate bottlenecks:
Previous conversational agents buckled under the weight of those combined steps. Traditional setups stitched together a speech-to-text engine, a standard text-based large language model, a separate text-to-speech voice clone, and an external video puppet renderer. The result was a disjointed three-second lag. By the time the avatar opened its mouth, the illusion was dead. The 2.80 Nvidia benchmark score reflected exactly that clunky, modular architecture. Tavus bypassed the Frankenstein stack by treating conversational sight, sound, and emotional cadence as a unified interaction problem.
Inside the engineering camps, researchers are zeroing in on the sheer statistical jump from a two percent pass rate to 48 percent on a live video feed. Observers tracking conversational interfaces point out that fooling a user on pure voice audio over a telephone line is already difficult, but pulling off the same trick on a bidirectional, high-definition camera feed removes the sensory safety net users have relied on for decades.
Tavus itself is framing the breakthrough not as a novelty demo, but as an operational necessity for real-world tasks that require human rapport. The company argues that existing automated systems fail because they treat conversations like a command-line prompt. You talk, it waits, it replies. In contrast, Griffin’s ability to catch physical micro-cues and mirror hesitation allows it to simulate actual empathy during volatile social exchanges.
Yet the response to Griffin's benchmarks is not universal celebration. Evaluators handling the Griffin-Lite preview note that crossing the uncanny valley at 3.83 points creates an immediate corporate trust hazard. When an automated persona scores just nine-hundredths of a point below a biological person, callers stop applying defensive scrutiny. They volunteer sensitive personal information, assume professional credentials that do not exist, and fail to verify claims made by the software.
Tavus acknowledges this exposure directly in its technical release documentation. The company explicitly conceded that the most capable iteration of Griffin cannot see general distribution until strict safety rails, identity guardrails, and misrepresentation mitigations are proven effective in live environments.
For the immediate future, Griffin remains caged behind enterprise pilot walls. Tavus has laid out three primary commercial deployment targets where it expects the technology to land first:
Moving from controlled 60-second trials to commercial production will test the limits of the HIM framework. In a one-minute cold call, a synthetic avatar can lean on polite introductions, brief conversational pleasantries, and scripted deflections to hide systemic hallucinations. Push that call duration to ten or fifteen minutes, and the cognitive cracks usually widen. The real hurdle for Griffin is whether its 48 percent deception rate survives sustained cross-examination when an angry IT customer or struggling student goes off script.
There is also the compute bill. Ingesting live video frames, processing facial geometry, maintaining an active speech pipeline, and spitting out real-time reactive video frames demands immense GPU muscle. Operating Griffin at scale across thousands of concurrent calls requires infrastructure that could prove economically crushing unless Tavus slashes inference overhead.
The regulatory landscape is equally hostile. Governments across North America and Europe are finalizing mandates that force autonomous systems to identify themselves upfront. If an avatar must legally declare, "I am an artificial intelligence" the second a call connects, the 48 percent illusion evaporates before the conversation starts.
Even so, the technical line has been crossed. The distance between synthetic video personas and live humans on a webcam is down to nine hundredths of a point. The voice AI market spent years trying to make machines sound human on the phone. Tavus just gave them a face, and half the world cannot tell the difference.
When synthetic agents cross from robotic voice prompts to photorealistic video that fools half the room, the operational barrier disappears. Voice interfaces are no longer isolated audio pipes; they are visual presences. The moment an avatar can maintain eye contact, catch a nervous pause, and respond without latency, enterprise customer service stops being an offshore call center problem and becomes a software infrastructure play. Any business banking on the awkward uncanny valley to alert users to artificial staff just ran out of road.
Reported off The Decoder. Original reporting and analysis by Ray Dalton for Vox Roboti.
Griffin is a real-time Human Interaction Model that processes speech, facial expressions, tone, gestures, and pauses during live bidirectional video calls.
In a one-minute video trial, 48 percent of test subjects believed Griffin was an actual human, up from two percent on older systems.
Griffin scored 3.83 out of 5 for human conversational feel, while actual people scored 3.92 and earlier models reached 2.80.
Only select testers have access to the Griffin-Lite preview, as Tavus is withholding the main model until safety risks are resolved.
Tavus designed Griffin for live interactive tutoring, practicing difficult workplace conversations, and visual, camera-assisted technical customer support.
The San Francisco-based company has raised approximately $64 million in funding since its launch in 2020.
Griffin handles video and voice input simultaneously, interpreting facial expressions, timing, and gestures while generating synthetic video output in real time.
Tavus held back the full release to address safety concerns regarding impersonation, deception risks, and caller trust.
Selma Ortiz · 17h ago · 4 min read
Cass Iverson · 2d ago · 5 min read
Selma Ortiz · 2d ago · 5 min read