Voice AI
Amazon Silently Kills Alexa Voice Switching for Older Echo AUX Jacks
Selma Ortiz · 16h ago · 4 min read
Google gave Gemini 3.8 Live an animated face that lip-syncs across 97 languages. The catch? You need an enterprise contract to touch it.
By Ray Dalton, Editor-in-chief · Reported off The Verge
Runs the desk. Allergic to demos that only work on stage.
Google spent years teaching its conversational models to talk. Now it wants you to look them in the teeth.
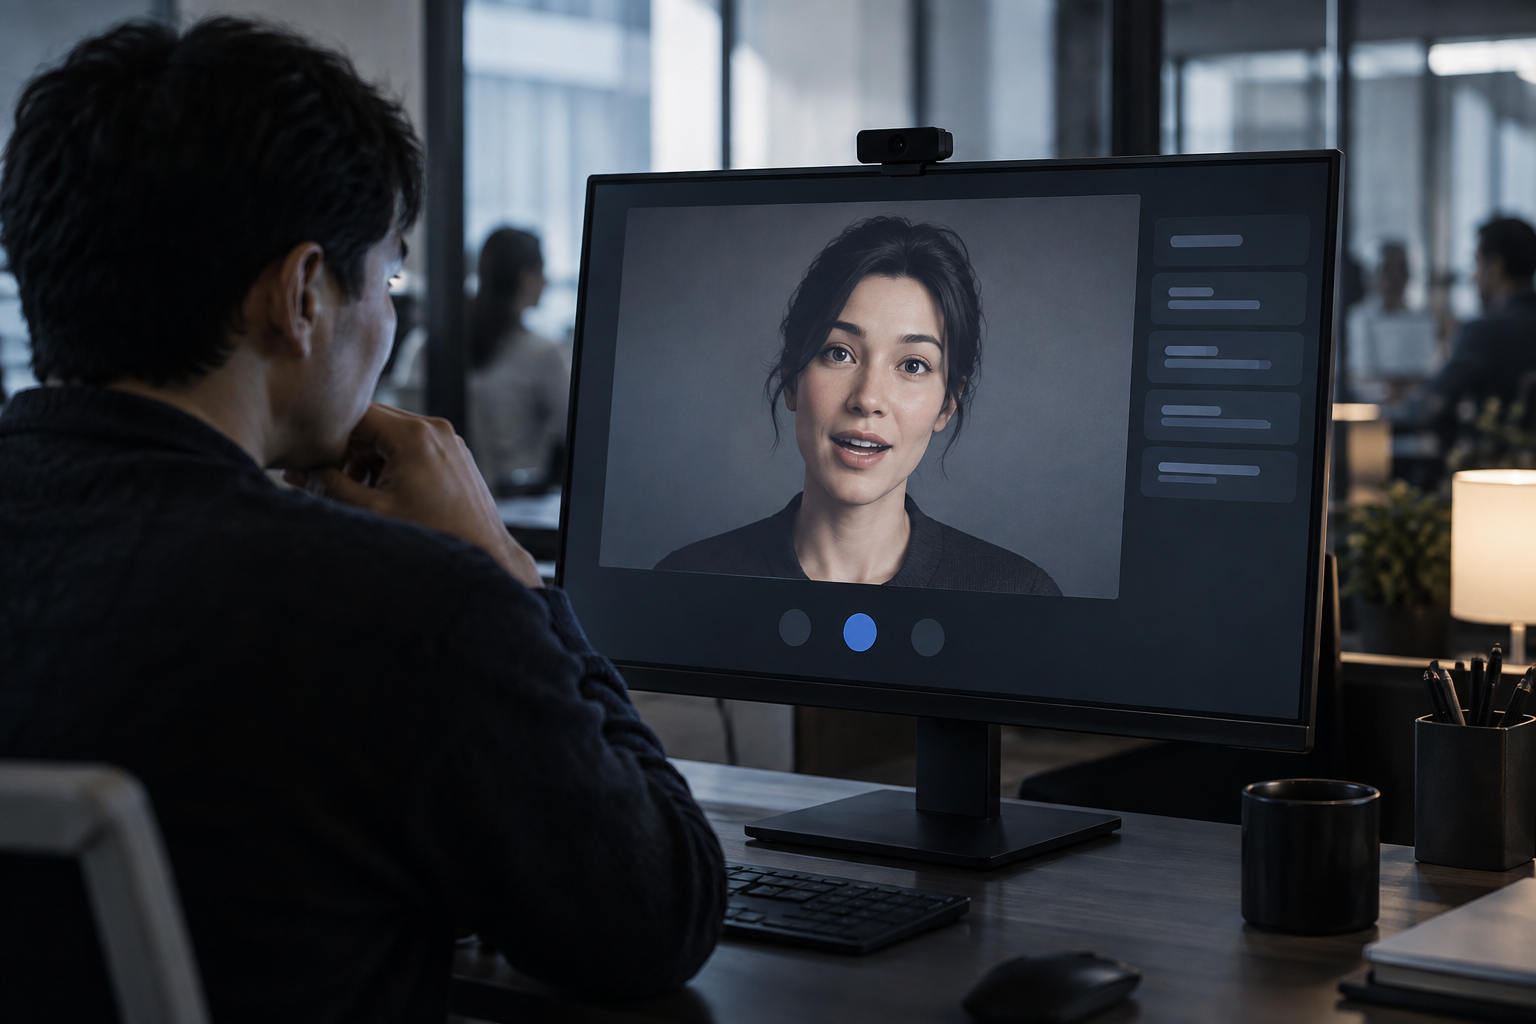
On September 24, 2026, the company launched Live Avatar, an animated visual interface for its Gemini 3.8 Live model. Instead of staring at an oscillating audio waveform or a pulsing circular glow, enterprise users talk to a generated persona that moves its lips, alters its facial expressions, and retrieves documents on screen while speaking. The product does not belong to the public. Google locked it behind the Gemini Enterprise tier, keeping the rollout strictly behind corporate firewalls.
Live Avatar takes the low-latency audio stack from Gemini 3.8 Live and welds it to real-time face generation. The system operates across 97 supported languages without visual drift, according to technical details shared by Google. During official demonstrations, the system toggled between English and Japanese speech, reshaping mouth geometry on the fly to match the phonemes of both languages without breaking video fidelity.
Corporate accounts get two deployment paths. They can select pre-built personas from an internal stock library, or they can use Google's pipeline to generate bespoke corporate avatars tied to their own brand guidelines. As the agent speaks, it also operates an interactive display layer, pulling up data and reference materials on screen beside the talking head.
To prevent the technology from turning into an unmonitored deepfake pipeline, Google applied two guardrails to the output stream:
Live Avatar maintains structural coherence across 97 languages without visual drift, pairing speech synthesis directly with visual phoneme tracking.
This release did not happen in a vacuum. It landed roughly one week after Google revealed the base Gemini 3.8 Live model. That underlying engine was designed to ingest and process inbound visual inputs in near real-time, giving the system visual awareness of user feeds before this generative visual frontend ever launched.
Adding real-time generated faces changes the computing economics of voice agents. Disembodied voice AI runs light. Audio models stream compressed tokens across low-bandwidth web sockets, with latency measured in milliseconds. Synchronous video synthesis demands substantially heavier GPU compute at the edge or the data center, requiring the server to calculate facial geometry, lighting shifts, and mouth tracking simultaneously while processing multimodal context.
Early interactive avatars from competing graphics startups failed on this exact threshold. They suffered from visual drift, an artifact where synthetic faces deform, lose eye alignment, or blur around the mouth when forced to sustain long interactions. Google built Live Avatar to bypass that visual degradation entirely, using the Gemini 3.8 foundation to maintain temporal consistency over long enterprise sessions.
Limiting the release to Gemini Enterprise also answers a legal question. Consumer-facing generative video tools attract immediate abuse, from non-consensual imagery to voice cloning fraud. By restricting Live Avatar to authenticated enterprise contracts, Google places liability and identity governance directly onto corporate IT departments before the code ever reaches open mobile apps.
Google frames the tool as an operational breakthrough for multinational organizations that need localized customer contact without regional visual lag. The company stresses that maintaining rendering fidelity across 97 distinct tongues allows a single corporate persona to operate across Asia, Europe, and the Americas without looking dubbed or disjointed.
Corporate buyers view the development through an operational ledger. Enterprise customer service directors want to know whether a rendered face increases customer retention or merely burns through server compute that a standard voice bot handles at a fraction of the cost. Frontline support desks run on margins, and rendering real-time generative video streams costs significantly more per minute than routing bare audio.
Security engineers remain focused on the provenance mechanism. While Google promotes its invisible SynthID watermarking as proof of synthetic origin, detection tools must reliably parse those markers across compressed video streams, third-party screen captures, and external recording software. If bad actors extract bespoke enterprise avatars to launch social engineering campaigns, the invisible tag must hold up under forensic scrutiny.
Multi-market enterprise teams, meanwhile, are scrutinizing the language transitions. The prospect of switching customer service sessions seamlessly between English, Japanese, and other markets without desynchronizing mouth movements solves a major localization bottleneck for global customer service desks.
The immediate proving ground for Live Avatar will be high-touch enterprise workflows: remote IT helpdesks, interactive product training modules, and multi-region banking interfaces. Google will use these initial corporate deployments to measure GPU loads and determine the operational costs of streaming continuous video avatars at enterprise scale.
If the enterprise tier proves profitable, Google faces immediate pressure to push the rendering pipeline down into the consumer Gemini app. OpenAI and other multimodal competitors have spent months tuning expressive, interruptible voice engines, but neither has attached an interactive, real-time video face to their consumer flagships. Controlling both sides of the duplex stream gives Google a proprietary wedge if it can scale the infrastructure.
Corporate developers must now grapple with identity architecture. Companies that choose to build bespoke avatars must establish clear policies regarding who owns the digital likeness, which executives or spokespeople can be digitized, and how access permissions are managed across internal teams. Once an enterprise gives its corporate AI a permanent face, retiring that persona becomes as complicated as firing a human executive.
Voice interfaces spent the last two years racing to zero latency. Google is now betting that disembodied audio is merely half an interface. By bolting synchronous, multilingual video synthesis directly onto an enterprise LLM, Google is forcing enterprise software vendors to decide whether voice alone is enough to hold a user's attention. If corporate buyers embrace real-time animated agents, the entire voice industry will have to pay the GPU tax to stay relevant.
Reported off The Verge. Original reporting and analysis by Ray Dalton for Vox Roboti.
It is an animated AI persona for Gemini 3.8 Live that talks, lip-syncs, and displays information in real time.
Only organizations with a paid Gemini Enterprise subscription can access the feature.
The system supports 97 languages without visual drift or loss of video quality.
Yes. Organizations can choose from a preset library or design custom avatars for their brands.
Google adds invisible SynthID watermarks to video frames and applies controls to protect individual identities.
Yes. The avatar can retrieve and display on-screen information alongside its spoken responses.
Selma Ortiz · 16h ago · 4 min read
Cass Iverson · 2d ago · 5 min read
Selma Ortiz · 2d ago · 5 min read