Voice Agents
Google Drops the Fitbit Edge and Tightens the Hardware Trap
Priya Raghunathan · 2d ago · 5 min read
Synthesia minted an interactive clone of a tech reporter to answer press questions. Behind the novelty sits a $4 billion enterprise engine built to replace human reps.
By Devon Achebe, Infrastructure reporter · Reported off TechCrunch AI
Follows latency, cost and the parts of the stack vendors hide.
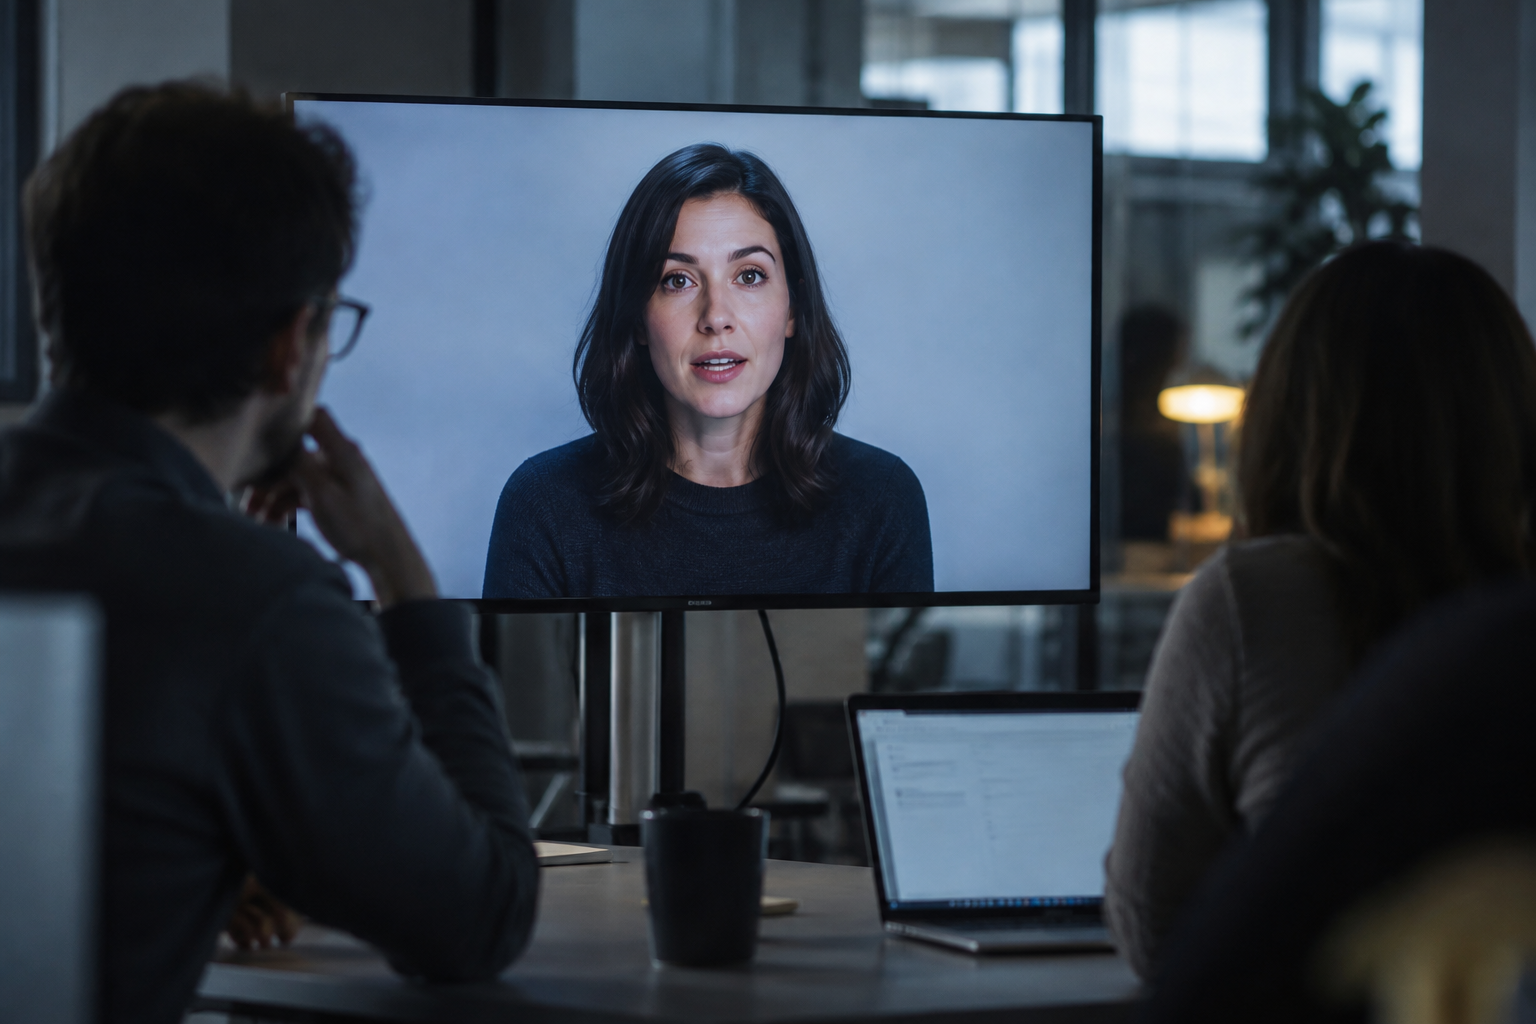
A reporter walked into a makeshift broadcast room inside Synthesia’s New York office, read text into a microphone for two minutes, sat for a camera burst, and walked out as a software package.
By late September 2026, Synthesia converted that raw audio and photographic capture into four distinct digital clones. Two operate as deterministic teleprompters: paste text into a box, and the synthetic figure reads it back with or without eyeglasses. The other two run as conversational voice agents. You speak aloud to them. They process what you said, query a narrow corpus of source material, and speak back in simulated real time with matching facial kinetics.
The test subject was Dominic-Madori Davis, a venture capital reporter at TechCrunch. Synthesia restricted her interactive twin to one reference text: an investigative piece she published analyzing why venture-backed startups commit fraud at higher rates than non-backed companies. If a user asks the digital persona why the story was written, what the underlying academic paper reveals, or what the findings show, the avatar answers. If the user asks about the reporter's personal history, location, or background before joining the publication, the model blocks the inquiry and pulls the user back to the fraud data.
The mechanics underneath the hood combine four separate pipeline layers:
Synthesia allows corporate buyers to swap its native voice and video components for third-party infrastructure. Buyers can plug in models from Cartesia, ElevenLabs, Google, or OpenAI, while running the deployment on Synthesia's servers or their own private cloud partitions. Davis represents the first working journalist cloned under this interactive framework, following an internal prototype built earlier in the summer for corporate affairs head Alexandru Voica.
Synthesia did not build this rig to entertain the press corps. The London-founded startup crossed $100 million in annual recurring revenue last year and commanded a $4 billion private valuation earlier in 2026. It wants to capture enterprise operational budgets.
The avatar sector is crowded. Synthesia trades blows against D-ID, HeyGen, and Colossyan for enterprise software contracts. The earliest iterations of these tools were simple video generators. An HR manager typed a compliance memo, chose a stock synthetic presenter, and exported an MP4 file. Synthesia classifies that baseline workflow as its legacy video-creation platform.
The commercial ceiling on static training videos is low. To justify a $4 billion valuation, Synthesia branched into two higher-margin areas: developer API integrations and an agentic training framework branded as Sessions. The Sessions product puts corporate employees in front of real-time conversational avatars to run simulations, evaluate sales pitches, and conduct automated exit interviews.
Voica road-tested the PR utility of this tech before opening the Manhattan studio to reporters. He rolled out an interactive synthetic twin trained entirely on Synthesia’s corporate fact sheet, capability list, and pricing structures. When reporters approached him for routine company background, he delivered a web link to his digital clone instead of booking a call. The experiment proved that a tightly ring-fenced voice agent could field predictable media queries without human labor.
The underlying economics explain the engineering choice. An enterprise spends thousands of dollars per employee per year running live roleplay workshops and fielding inbound customer queries. Synthesia is positioning deterministic voice-to-video pipelines as a replacement for that human overhead. The platform provides the avatar rendering while allowing corporations to hook their existing enterprise knowledge bases and preferred voice vendors into the backend.
The immediate user reactions expose the gap between corporate capability and human comfort.
When Davis tested her static script-reading replica, the synthetic voice stripped out the hoarseness present in her physical vocal cords during the recording session. The synthetic voice delivered clean sentences about autumn in New York. When she shared the conversational twin with civilian friends outside the tech sector, the response was immediate unease. Test subjects described the interactive model as uncanny, pointing out that its conversational voice clone drifted further from her true cadence than the static script-reader did.
Family members tested the conversational boundaries. Davis's parents interrogated the model using personal queries that only the real reporter could answer. The deterministic system rejected every prompt, rerouting the conversation back to venture-backed corporate fraud. Her mother joked:
I don't remember giving birth to two of you.
Industry sources Davis interviewed expressed skepticism about synthetic replacements in public-facing roles. An enterprise investor dismissed the idea that consumers would tolerate avatar-driven news delivery. Davis noted the growing resistance against synthetic content farms across digital publishing, arguing that while enterprise clones can eliminate backlogged work after vacations, journalistic credibility relies on direct human relationships that cannot be delegated to deterministic software.
Davis also flagged a psychological divide between deterministic clones and open-ended generative models. A bounded model that only recites verified story facts feels like an interactive archive. An unbounded, conversational agent free to improvise poses a different risk, increasing the likelihood of cognitive dissonance or synthetic delusion among users who spend hours conversing with simulated humans.
The novelty of cloning tech reporters will burn off quickly. The real conflict sits inside corporate enterprise software stacks.
Synthesia is targeting sales enablement, customer support, and internal compliance training. The company wants companies to stop paying human coaches to train sales reps. If an enterprise sales rep can pitch an interactive avatar built on Synthesia Sessions, receive automated performance scoring, and drill objection handling fifty times before talking to a buyer, companies will cut human training budgets. The integration of low-latency voice engines like Cartesia and ElevenLabs removes the robotic pauses that made earlier conversational video unwatchable.
The deterministic constraint is the feature, not the bug. Corporate legal teams will not deploy open-ended generative avatars capable of inventing corporate policy or making unauthorized product claims. By forcing the Davis avatar to answer strictly from the source text of one article, Synthesia demonstrated its compliance guardrails. The system trades conversational range for factual containment.
Gen Z users and media consumers present a harder barrier. Davis observed that younger digital natives, who grew up consuming endless synthetic social feeds, are developing an aversion to synthetic video slop. Watching a computer-generated head talk on a screen feels cheap. It carries the stench of mass-produced marketing collateral.
Where this tech lands is obvious. High-friction, high-trust human labor—like investigative journalism, executive dealmaking, and confidential reporting—will stay human because sources demand real accountability. Low-friction, repetitive information retrieval will be swallowed by synthetic faces. Your next corporate training seminar, technical documentation query, or tier-one customer service dispute will not be handled by an overseas contractor or a text chatbot. It will be an interactive avatar, trained on an exact company handbook, speaking in flawless cadence, and incapable of going off script.
Putting a journalist's face on a voice agent makes for great PR, but the real target is the enterprise support desk. Synthesia is taking the voice models developed by Cartesia and ElevenLabs, attaching deterministic lip-synced faces to them, and selling them to enterprises looking to eliminate live corporate training and customer service reps. If you work in repetitive corporate education, software demonstration, or level-one support, software is coming directly for your seat.
Reported off TechCrunch AI. Original reporting and analysis by Devon Achebe for Vox Roboti.
It is a digital clone that listens to speech, reasons through an assigned text, and speaks back with synchronized video movements in real time.
The initial data intake requires two minutes of voice audio and a sequence of still photos in a studio space.
No. The interactive model is deterministic and only answers questions based on a specific research article about venture-backed startup fraud.
Synthesia uses its own speech and video engines, but clients can integrate third-party models from Cartesia, ElevenLabs, Google, or OpenAI.
Synthesia reached a $4 billion private market valuation earlier in 2026 and passed $100 million in annual recurring revenue last year.
Synthesia competes directly against digital video avatar providers including D-ID, HeyGen, and Colossyan for enterprise corporate training budgets.
Sessions is an interactive agentic platform that lets enterprise employees roleplay conversations, practice sales pitches, and receive automated scoring from avatars.
Priya Raghunathan · 2d ago · 5 min read
Nina Falco · 3d ago · 5 min read
Devon Achebe · 4d ago · 4 min read